What our experimental self-healing software loop shipped in two weeks
We ran a pilot between September 18 and October 1 of a self-healing loop pieced together from three services, running on our own repository. The loop opened 152 pull requests, none of them written by a human. Brian Hackett, our CEO, reviewed and merged 80 of them, each with its fix verified, without any extra testing on our side.
How the loop is wired
Each of the loop's three layers does the one job it is good at. Fullstory is the production monitoring layer: it watches real sessions and flags when something is wrong. Replay QA replays the user sessions to find the root cause and supporting evidence, and generates bug reports. Our software factory (powered by Obvious.ai) writes the fix. Then someon on the team, typically Brian, CEO, reviews the PR and the QA report and decides whether to merge.
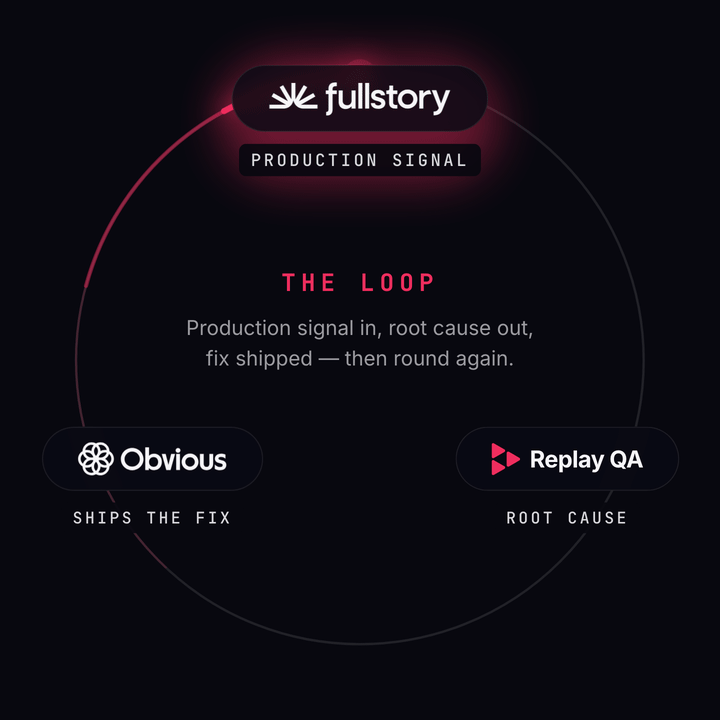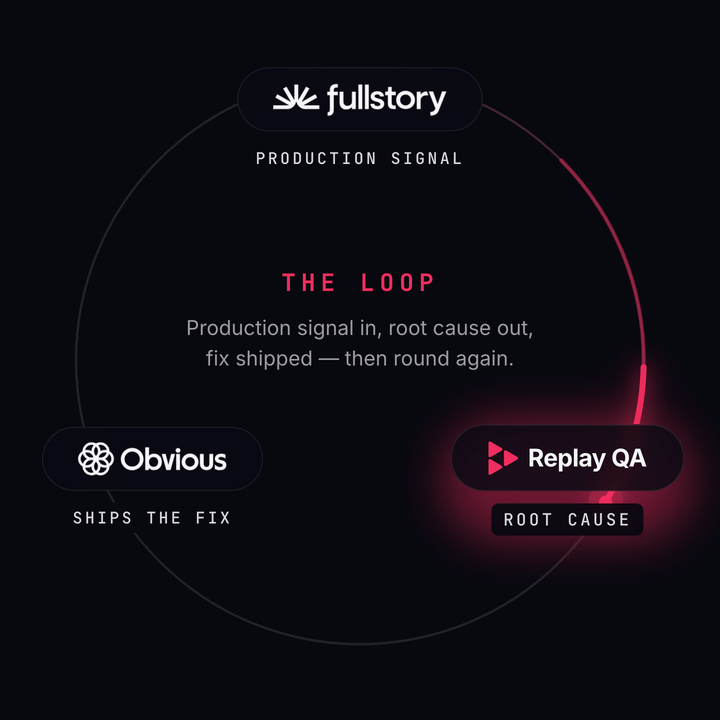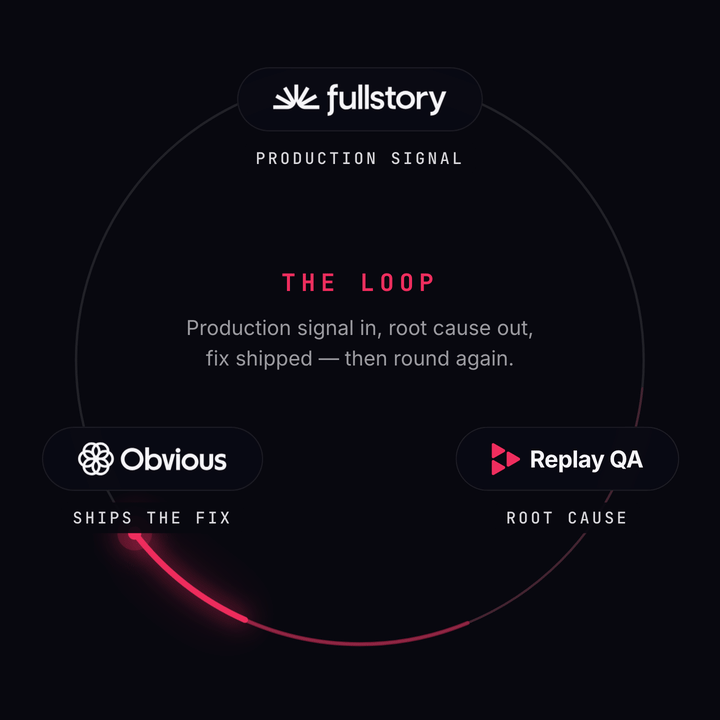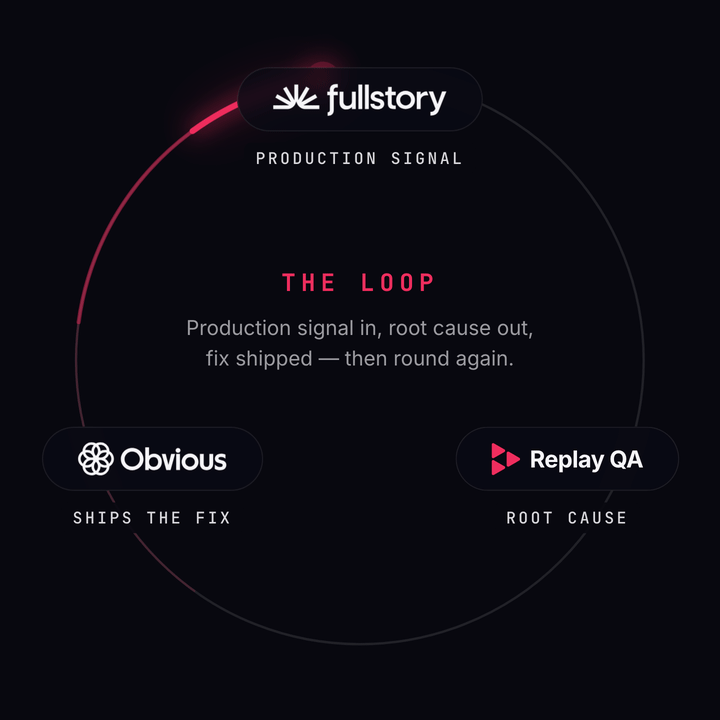
- Detect (Fullstory): surfaces the signal from real production sessions.
- Diagnose (Replay QA): reproduces it, finds the root cause from the recording, and files a GitHub issue with severity, evidence and a bug ID.
- Fix (Obvious): opens a PR on
fix/qa-issue-Nwith the why, what changed and the tradeoffs, linked byFixes #N. - Verify (Replay QA): explores the PR preview for regressions, then reproduces the original bug against it: replaying the original session for frontend changes, reproducing it independently for backend changes.
- Merge (Brian): reads the PR and the QA report and decides. On merge, the issue closes automatically.
Steps 2 and 4 are the same mechanism. Replay QA reproduces the bug once to diagnose it, and again against the PR to prove the fix.
Where the 152 PRs went
Here is where every one of the 152 pull requests ended up.
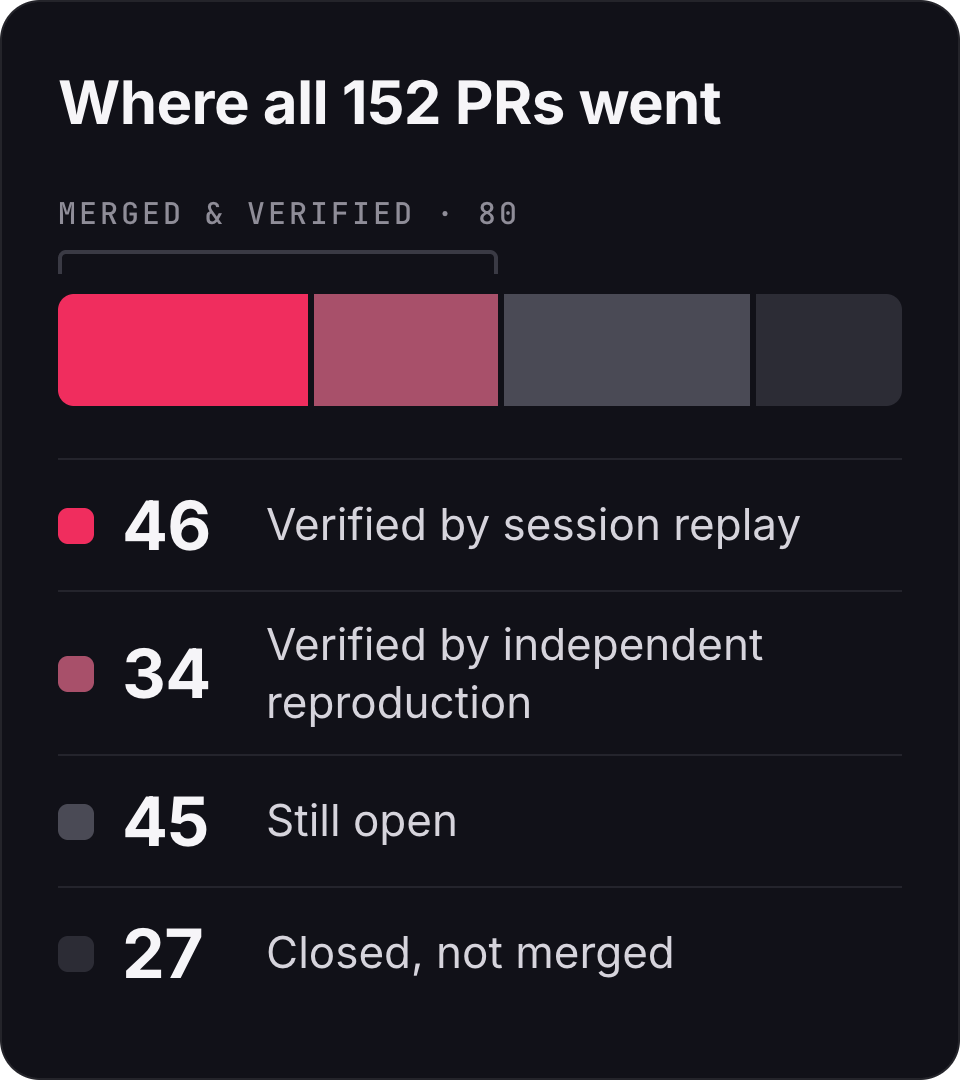
All 80 merged PRs came with the original bug reproduced against the PR and shown to be gone. For the 46 frontend changes, that meant replaying the session that found the bug. For the 34 backend changes, Replay QA reproduced the problem independently.
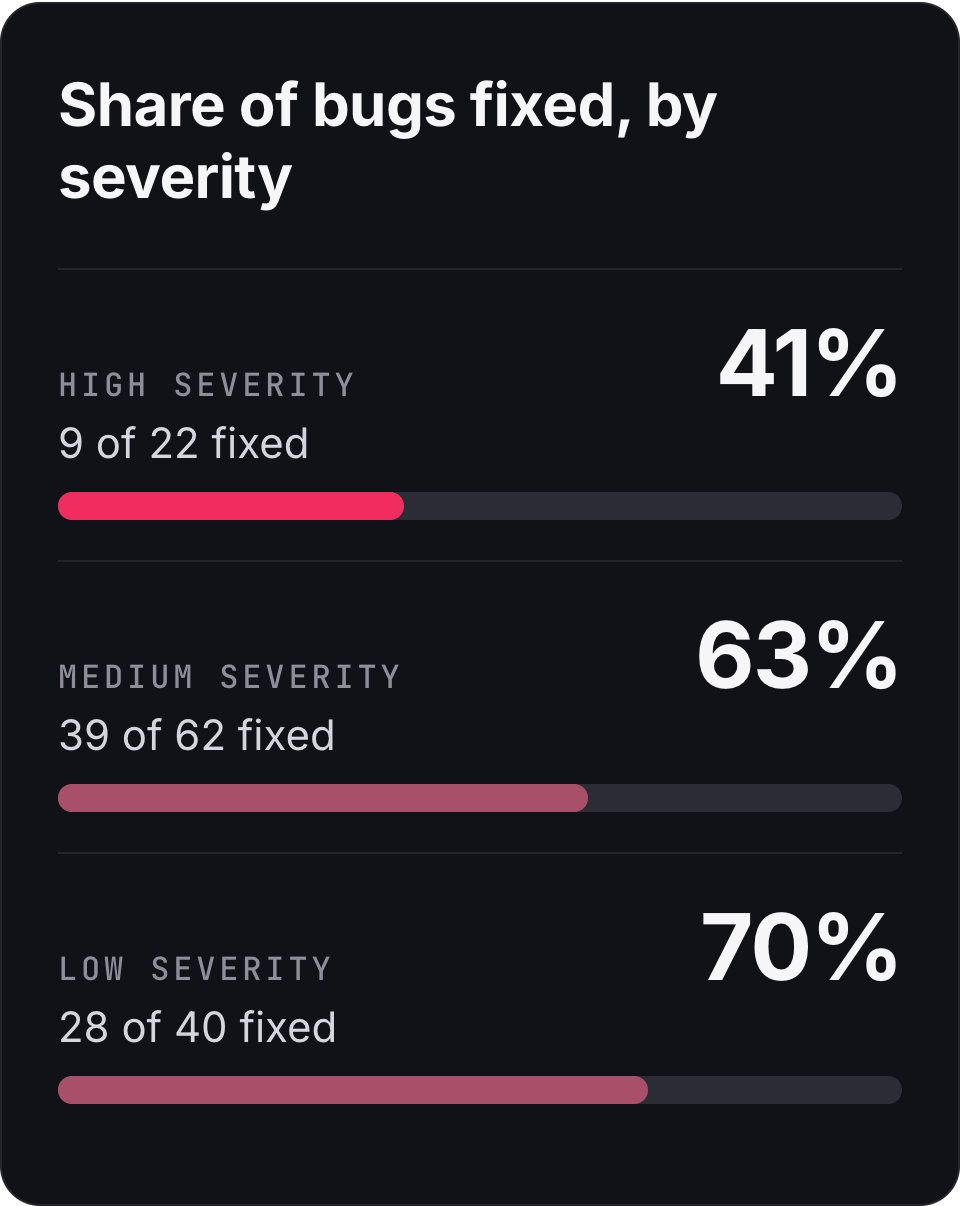
Underneath the PRs are 124 distinct bugs, and 76 are now fixed on main. That is a little over five bugs fixed a day with nobody writing the code. Eighteen of the 124 needed more than one attempt, because when a PR was closed or failed QA, the loop opened another one. One Segment PII leak took four tries.
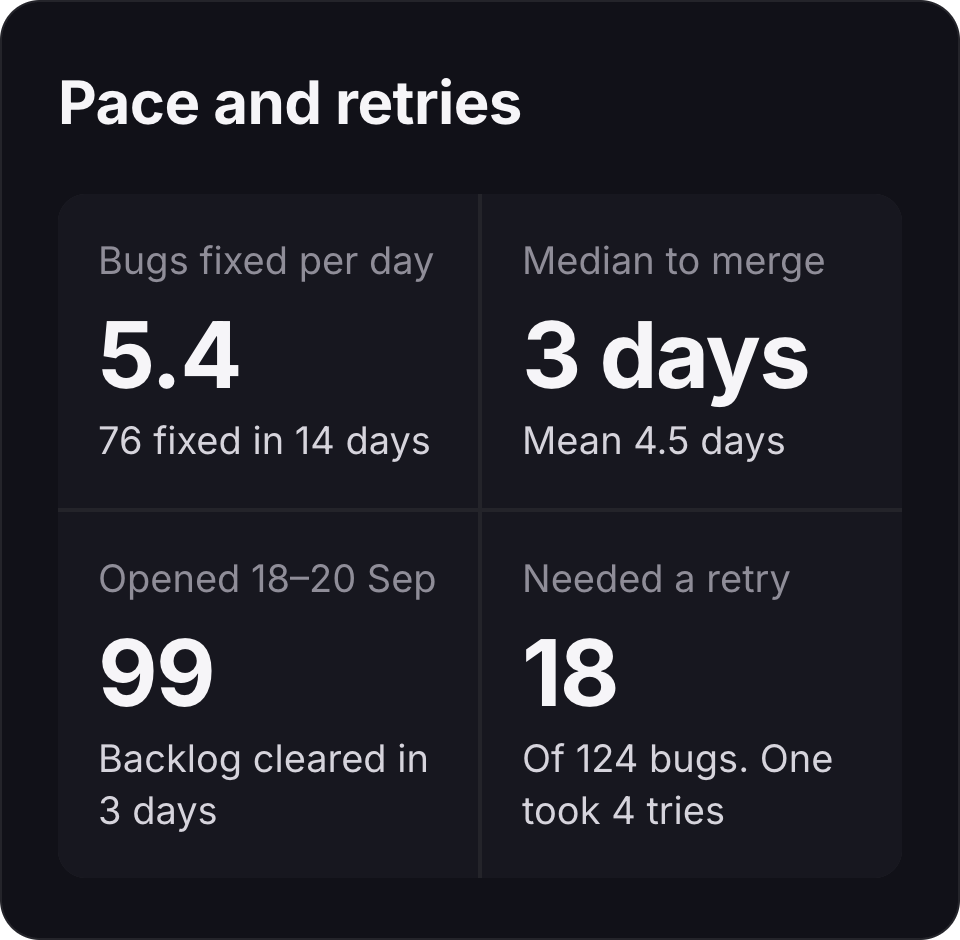
Most of the 27 closed-without-merge PRs are those superseded attempts, not outright rejections. After the first three days cleared the backlog, merges kept pace with new PRs. One note on scope: seven of the 152 PRs have no linked QA bug. They are follow-ups, mostly the loop repairing CI on one of its own earlier PRs.
What a loop like this is good at
The 124 bugs, grouped by type. Two things in this chart surprised us.
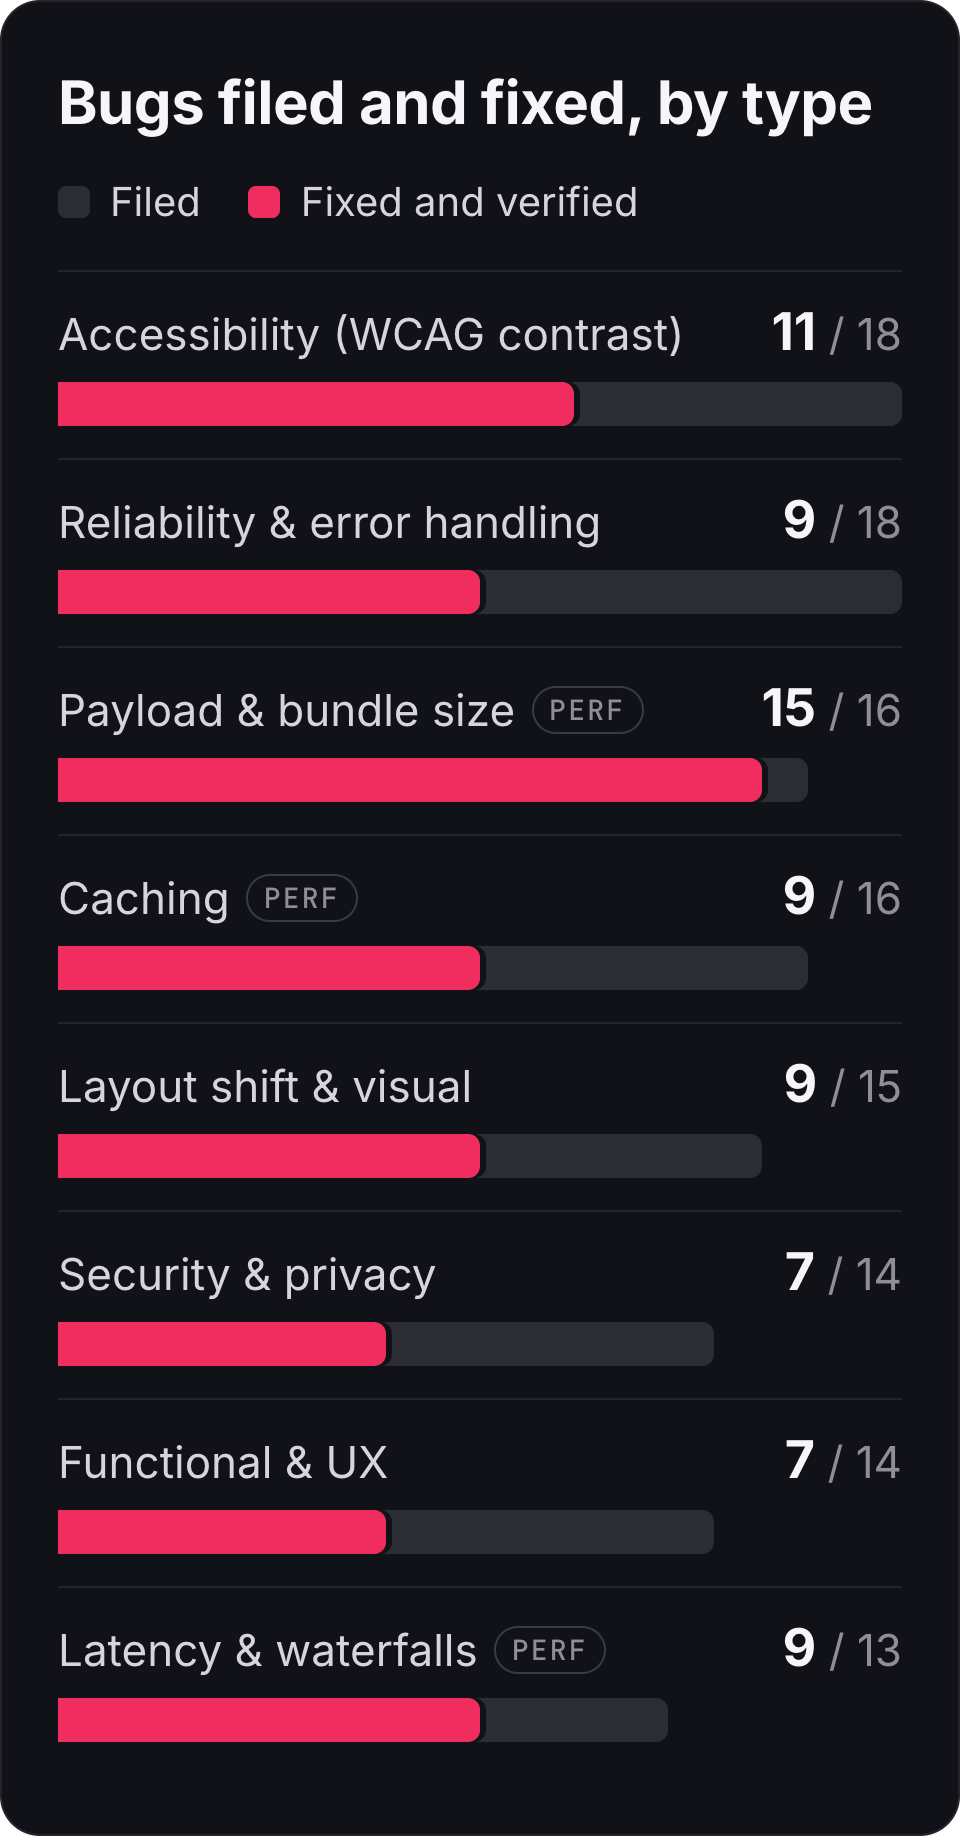
Performance is 43% of everything the loop fixed. That covers oversized payloads, API responses served no-cache and request waterfalls. One response was shipping about 975KB of journey-authoring trees on every project view. Bugs like these sit in a backlog for a year because no single person owns them and none of them is ever the most urgent thing. A loop does not care that they are boring.
Security bugs had the crispest reproductions. A security bug tends to fail in an unambiguous way, so proving the fix is unambiguous too. The fixes included GET /api/projects returning the private project list with a 200 and no authentication; unauthenticated project reads returning the full record, including owner_id; and /api/auth-me, which carries email and Auth0 id, being served stale from a CDN cache about 132 seconds later despite no-store.
Two ways to prove a fix
To verify a fix, Replay QA reproduces the original bug against the PR preview and checks that it is gone. How it reproduces the bug depends on what the PR changed.
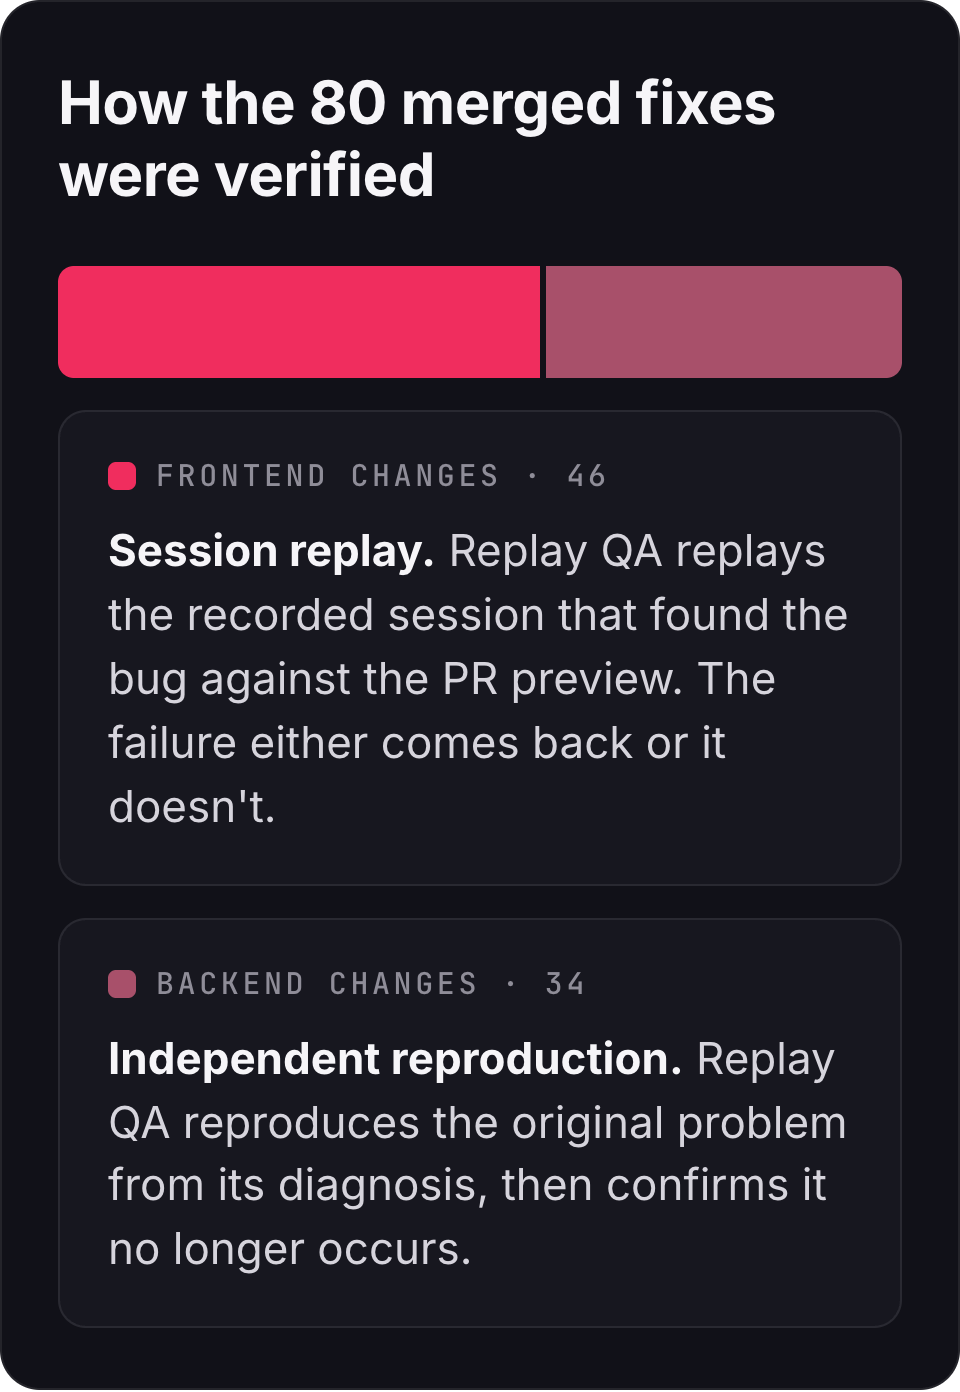
Either way, Brian was not asked to trust a model's account of its own fix. Each PR he merged came with the original failure reproduced against the change and no longer happening.
Opening PRs was the cheap part. The 80 that merged had that proof attached.
Chris Kelly's replayable trace
While writing this up, we looked for anyone who had described the stage that made this work. The closest we found is a sentence from Chris Kelly, Head of Developer Experience at Augment, in his guide to building a software factory for LeadDev on 10 September:
A verifier deploys to an isolated instance, exercises the affected behavior, and posts inspectable proof — logs, screenshots, a replayable trace.
— Chris Kelly, Augment · LeadDev, 10 Sep 2026
The third item on that list is the hard one.
A factory already has logs and screenshots. Those report an outcome. A replayable trace is the artefact that lets a human, or a second agent, go and check. We read the published descriptions of agentic software factories, including Cloudflare's, Vercel's, Builder.io's, Augment's, OpenAI's and Uber's. Most have no reproduce-or-diagnose stage at all. Of the handful that do, Kelly's is the only one we have found that says what the stage should produce.
As far as we can tell, he is also describing something nobody ships today. Vercel's documentation describes the same limit: investigation can reproduce a failure before implementation starts, but for bugs that need a browser, every browser session runs with a person present, and an unattended run falls back on recorded findings.
The only hard numbers we know of come from Google's automated-program-repair team, who measured both halves of this (arXiv:2502.01821).
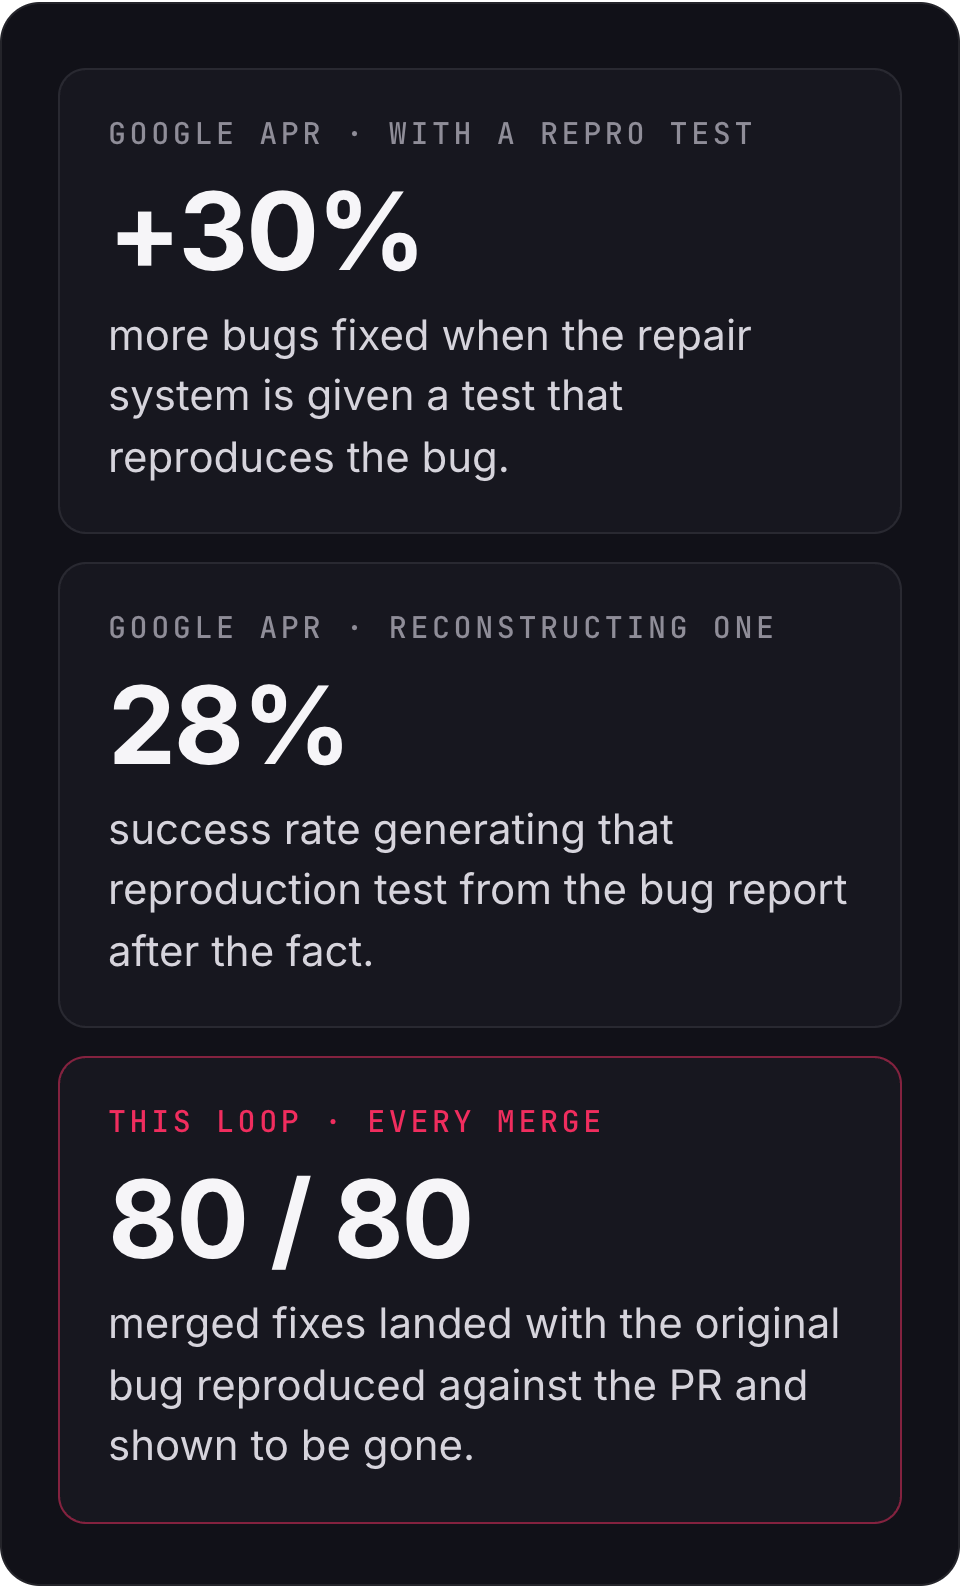
Reproduction was the highest-leverage input they measured, and reconstructing one was the step that failed. In follow-up work, they note that their own engineers, using the deployed system, asked for the reproduction test to be included in the AI-generated patch, because that is what made them willing to trust it.
Our two weeks are a small, concrete version of the same finding. For the 46 frontend fixes, nothing had to be reconstructed: the session that found the bug was recorded as it happened. For the 34 backend fixes, the loop did the harder thing Google measured and reproduced the failure independently. A self-healing loop is only as good as its ability to reproduce the failure a second time.
Want to try Replay QA on your app?
Replay QA autonomously tests your web app, finds real bugs, and delivers root-caused reports your team can act on. No test suite required.
Try it now for free